That creates an vital blind spot.
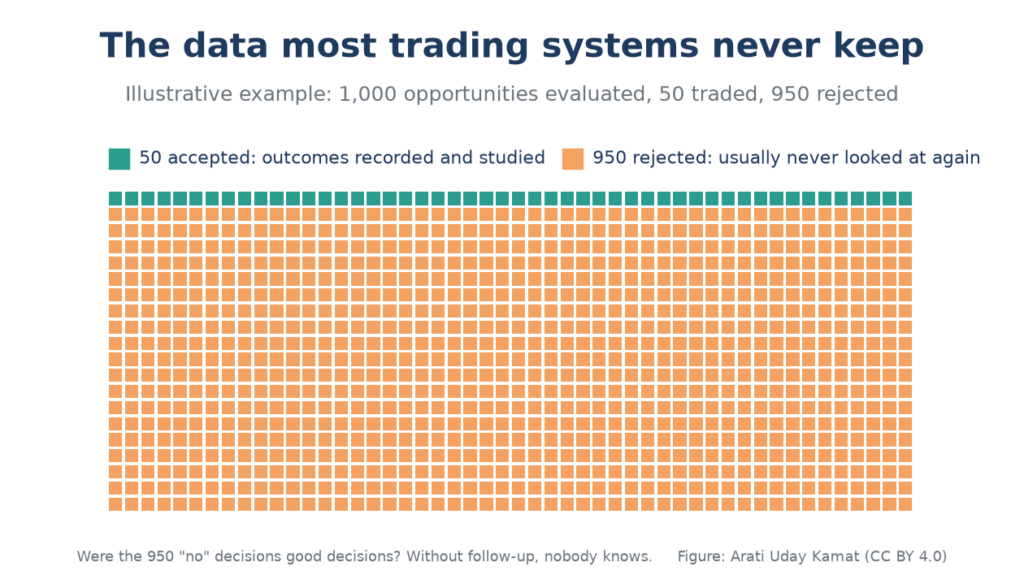
Think about an automatic crypto buying and selling system evaluates 1,000 attainable alternatives and rejects 950 of them. It executes solely 50 trades.
The developer can fastidiously analyse the efficiency of these 50 trades. However that also doesn’t reply a primary query:
Had been the opposite 950 rejections good selections?
A filter could seem to guard a buying and selling system as a result of the trades it accepts carry out moderately nicely. However with out observing what occurred after rejection, no one can know what number of losses the filter efficiently averted or what number of doubtlessly worthwhile alternatives it discarded.
This drawback turned more and more vital to me whereas learning algorithmic decision-making on decentralised exchanges.
A buying and selling system doesn’t make selections solely when it buys or sells.
Selecting to not commerce can also be a call.
Suppose a token is rejected as a result of its liquidity is simply too low. One other is rejected due to pockets focus. A 3rd fails a momentum threshold.
Twenty-four hours later, the primary token collapses, the second turns into inactive and the third rises sharply.
These outcomes comprise details about the filters that made the unique selections.
But when the system stopped observing every token in the mean time it rejected it, that info has been misplaced.
This creates an asymmetry within the knowledge.
Accepted selections naturally generate histories as a result of capital is connected to them. Rejected selections can disappear from the document despite the fact that they might significantly outnumber accepted ones.
I wished to measure that lacking aspect of the choice course of.
I developed Publish-Rejection Comply with-up Sampling, or PRFS, as a framework for doing this systematically.
The essential thought is straightforward.
When an algorithm rejects a candidate, don’t throw the candidate away.
Document the choice and proceed observing the asset.
The method can protect the time of rejection, the rationale for rejection, the market situations seen at that second and subsequent observations at predefined intervals.
The order issues.
The choice comes first. The next market path is noticed afterward.
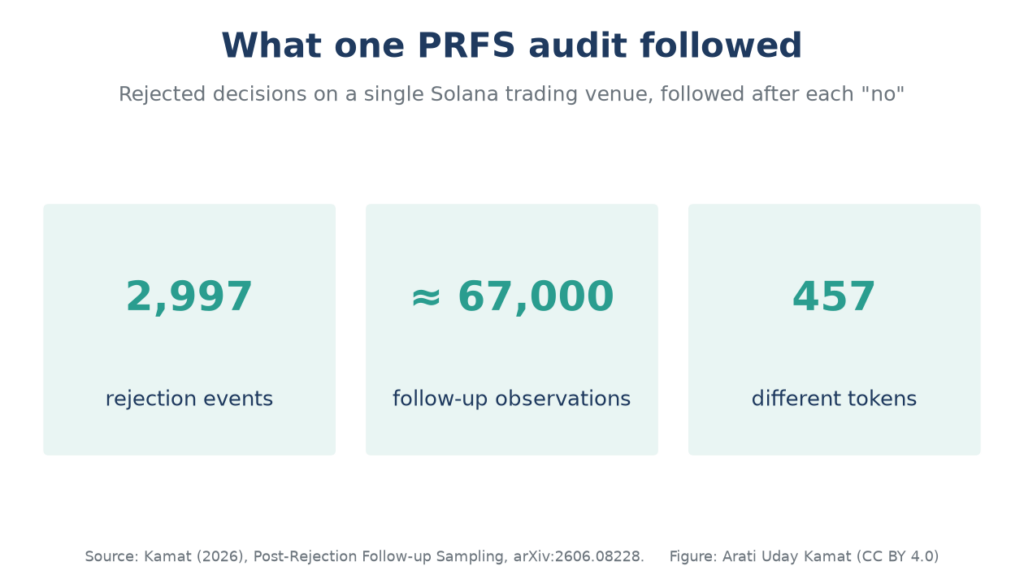
In my PRFS audit, the dataset contained roughly 67,000 ahead observations related to 2,997 rejection occasions involving 457 distinctive token mints.
The audit additionally uncovered one other vital lesson.
Accumulating extra knowledge doesn’t routinely remedy a measurement drawback.
The id of the choice being adopted, the timing of observations and the way in which these observations are linked again to the unique rejection all matter.
A big dataset can nonetheless reply the flawed query if these relationships are incorrectly recorded.
I additionally developed RED-2400, a public benchmark designed round algorithmically rejected buying and selling occasions.
The target was to not produce one other buying and selling technique or declare that one filter might predict token costs.
It was to make the rejected aspect of the choice course of observable.
As soon as that info exists, researchers can ask a lot better questions.
Did a selected filter largely reject belongings that subsequently deteriorated?
Did it repeatedly discard belongings that later appreciated?
Did its effectiveness change below totally different market situations?
Are a number of filters rejecting primarily the identical inhabitants for various causes?
And maybe most significantly:
Is a buying and selling system being improved primarily based solely on the small fraction of alternatives that the system itself made observable?
One of the crucial encouraging developments has occurred exterior my very own analysis.
Unbiased builders have since constructed rejection follow-up ledgers and associated post-rejection monitoring into their very own programs.
Some have created persistent ledgers for rejected indicators quite than permitting these selections to vanish from course of reminiscence. Others have applied post-rejection trackers that proceed observing rejected candidates at predefined intervals in order that screening guidelines can later be evaluated towards what really occurred.
Different unbiased researchers have used public knowledge from my work to research choice and survivorship bias in their very own buying and selling datasets and technique experiments.
This issues to me as a result of analysis turns into way more informative when somebody aside from its creator tries to make use of it.
An exterior implementation can expose limitations, reveal new functions and generally present that an apparently promising technique shouldn’t be deployed in any respect.
That final final result deserves extra consideration.
Monetary analysis is usually offered as worthwhile when it discovers one thing worthwhile.
However figuring out one thing that shouldn’t be deployed may also have financial worth.
Suppose a method seems worthwhile in historic knowledge.
A broader dataset then reveals that profitable belongings had been disproportionately represented within the unique pattern. Or a extra life like replay exhibits that the obvious benefit disappears after transaction prices.
The helpful result’s not a worthwhile backtest.
The helpful result’s avoiding a doubtlessly dangerous determination.
That is particularly vital in fast-moving crypto markets, the place small samples, altering liquidity and choice results can produce enticing historic outcomes that won’t survive real-world situations.
A system able to discovering proof towards its personal selections could finally be extra helpful than one designed solely to seek out obvious winners.
Reject-side measurement isn’t solely a cryptocurrency drawback.
Contemplate credit score underwriting.
A lender naturally observes compensation efficiency for authorised debtors. The outcomes of rejected candidates are a lot more durable to watch below the identical lending determination.
Contemplate fraud detection.
Instances that move by way of later phases of investigation could generate wealthy labels, whereas circumstances eliminated earlier within the pipeline can obtain a lot much less follow-up.
Comparable issues can seem in insurance coverage, threat screening, advice programs and different machine-learning functions.
The main points differ, however the underlying drawback is said.
Automated programs more and more filter giant populations earlier than taking motion on a a lot smaller subset.
If researchers consider solely the inhabitants that survives these filters, they might find yourself evaluating a inhabitants partly created by the system itself.
As monetary programs grow to be extra automated, I imagine their audit trails ought to protect greater than executed actions.
Rejected selections ought to grow to be first-class knowledge.
What did the system see?
Why did it say no?
What occurred afterward?
Was the rejection finally in line with the system’s goal?
And does the identical rule proceed to behave equally when market situations change?
These questions grow to be much more vital as monetary decision-making strikes towards machine-learning fashions and more and more autonomous brokers.
A buying and selling algorithm that information solely its trades remembers what it did.
A system that additionally follows its rejections can start to measure whether or not its selections had been really helpful.
The info at present discarded could comprise a number of the most vital details about whether or not automated monetary programs deserve confidence.
This text is for info solely and isn’t funding recommendation.
Publish-Rejection Comply with-up Sampling (PRFS): arXiv:2606.08228
RED-2400: arXiv:2605.12151
Arati Uday Kamat is an unbiased researcher engaged on algorithmic decentralised-exchange buying and selling, reject-side final result measurement and financial-system analysis. Her research consists of Publish-Rejection Comply with-up Sampling (PRFS), arXiv:2606.08228, and RED-2400, arXiv:2605.12151, a public benchmark for learning rejected buying and selling selections.
Arati Uday Kamat Arati Uday Kamat Read More